RollupDB 0.5 Counts Retried Batches Once and Takes Prometheus Remote Write
RollupDB 0.5.0 is out, and most of it is about one awkward moment. A batch goes in, the connection drops, and you don’t know if it committed. Until now the docs said: don’t retry blindly, you might count everything twice. That’s honest, but it isn’t much help at three in the morning.
So a batch can now carry an ID. RollupDB stores the ID, a hash of the readings and the result in the same transaction as the data. Send the same batch again and you get the first answer back, marked "replayed": true, and nothing changes. Send different readings under the same ID and it’s refused with batch_conflict, which is what you want if two jobs ever end up sharing a name.
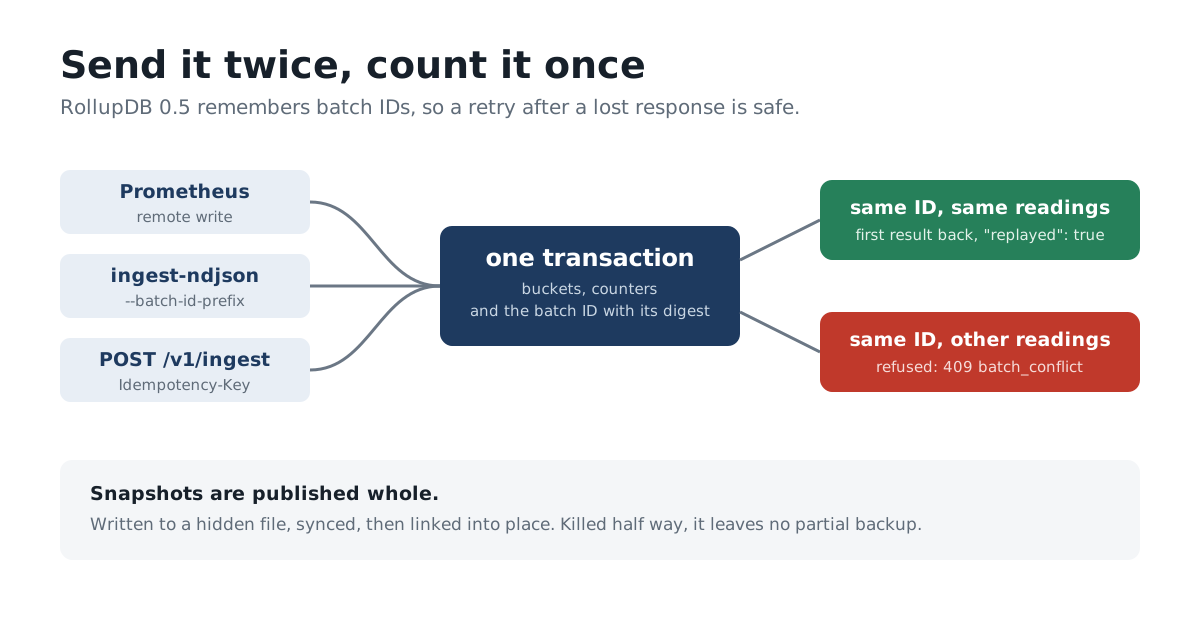
Over HTTP it’s a batch_id field or an Idempotency-Key header. On the command line, ingest-ndjson --batch-id-prefix nightly names every batch after its first line. If an import dies half way, run the whole thing again with the same prefix and batch size; the committed batches replay and only the rest is written. IDs are kept for seven days and rollups clear out the old ones.
Prometheus, Without a Bridge
People with metrics already in Prometheus had no way in short of writing their own exporter. Now rollupdb serve --remote-write map.json takes remote write 1.0 directly. The map file says which metric goes to which stream and which label fills each dimension, and the server checks it against the database before it starts listening.
Batch IDs are what make this safe. Prometheus retries any request that gets a 5xx, and before 0.5 a retry after a partial failure would have double counted. Each batch’s ID comes from the request body, so a retried request replays what already made it in and only writes the rest. The snappy and protobuf decoding is written by hand, so there’s still no new dependency, and it’s tested against payloads produced by the official protobuf library and a separate snappy encoder.
The independent review earned its keep here. It found that a 3 MB request could unpack into gigabytes of empty series, that a stream update between a failure and the retry turned the retry into a conflict (and Prometheus would drop it), and that samples dated before a stream’s start would make Prometheus retry forever. All of those are fixed, each with a test, and requests are now capped at a million samples.
Snapshots That Appear Whole
A killed snapshot used to leave a half-written file under the name you asked for. Now the copy goes to a hidden file in the same folder, gets synced, and only then is linked into place. The tests kill a snapshot after the copy is written and again in the middle of writing it; both times there’s nothing under the destination name, and the next snapshot works.
The format moves to revision 5 for the new batch table. Files from 0.4 and earlier need one rollupdb migrate FILE (back up first), which adds the empty table and changes nothing else.
The download page has the binaries and the reference has the details. The code is on GitHub.